
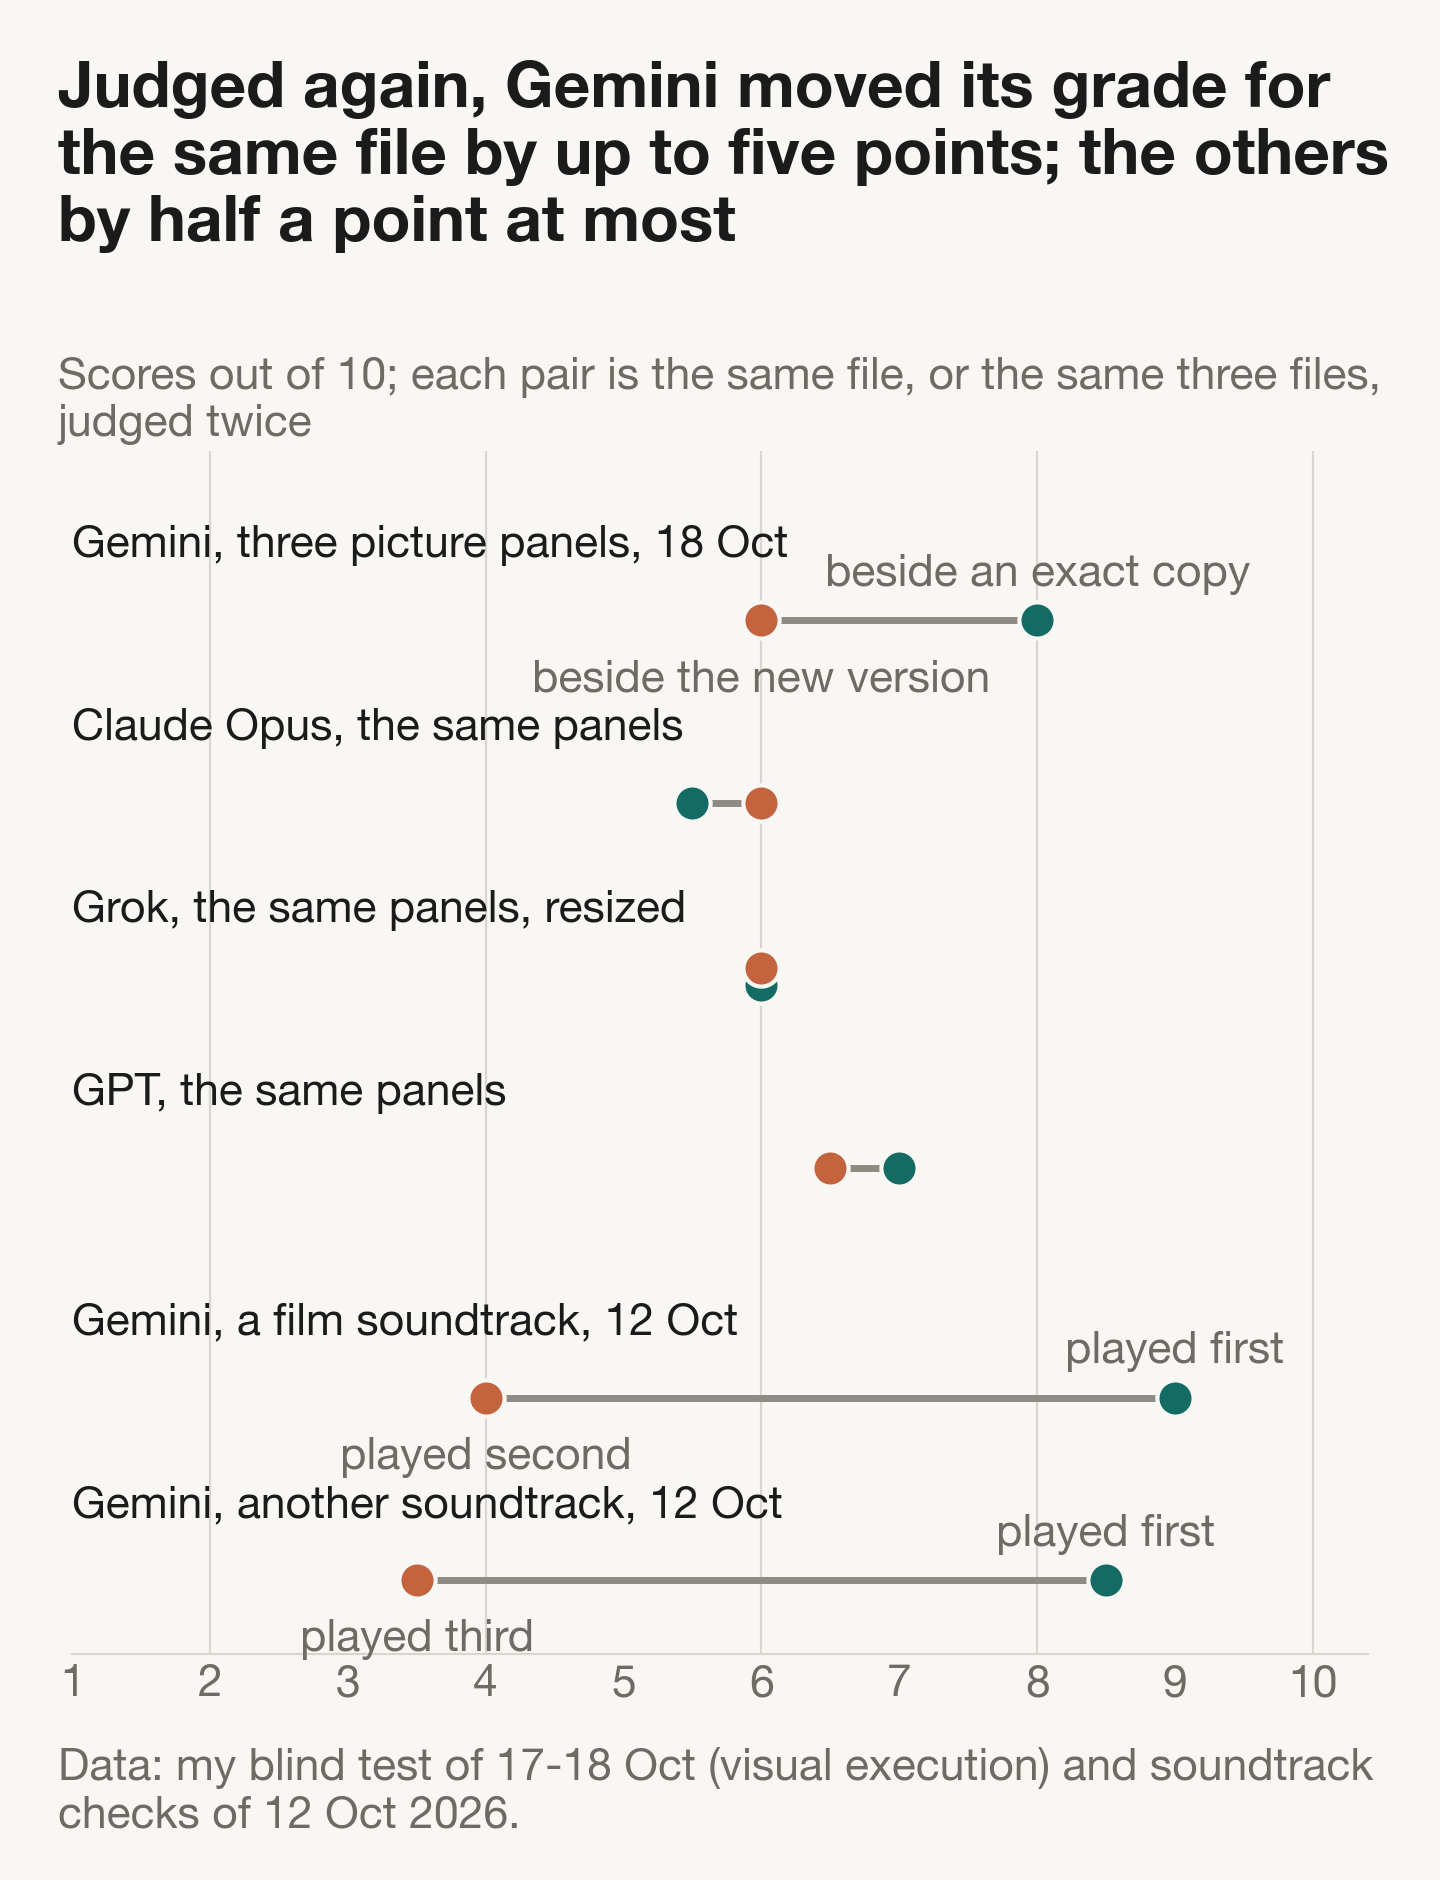
An AI model gave three of my pictures an 8 out of 10. Two minutes later it gave the very same files a 6. I rely on judges like it, so I went looking for what else they are grading.
Drafted with AI assistance; however, every number, failure, and opinion in here is mine
One Sunday morning in October, Gemini looked at three pictures from one of my illustrated products and rated how well they were drawn: 8 out of 10. It praised the "clean ink and colouring lines" and the lanterns that glowed warm and cosy. Two minutes later it got the same three files again and gave them a 6. The clean lines were now "vague, empty squiggle lines". The lanterns hung "illogically in the sand". I checked whether the files really were identical, down to the last byte, because I did not believe it either. They were.
Nothing about the pictures had changed. The picture next to them had.
My company is one person and a crew of AI agents, and a lot of what the agents make is visual: a picture book, a large hidden-object scene, a fox burrow you can explore in the browser, short films with music. I can't inspect all of it, so other AI models look first. I call them judges. A judge gets a picture, a film or a sound file plus a question, and answers with a score and a few lines of notes. Some judges are gates that send work back to the agent that made it. Others give opinions I read before I decide.
In September I had turned Gemini Flash down as a judge for my social-media bot, because it gave nearly every picture the same grade. A judge that gives one grade to everything, I argued then, isn't really judging. By October its grades moved plenty, more widely than any other judge's in the test I am about to describe. That Sunday I found out one thing that was moving them.
The Blind Test
The three pictures came from a test I ran that weekend. My agents had rebuilt seven illustrated works, partly to improve them and partly to cut the bill: most new pictures came from a free image tool instead of a paid image model. Claude Opus from Anthropic, Grok from xAI and Gemini from Google saw old and new side by side, without being told which was which. GPT from OpenAI sat in as a fourth voice that didn't count. The verdict was nearly unanimous: the new versions won 19 of 21 votes. A vote only meant the judge picked the new version, however narrowly.
I made my own pass, and I wasn't blind: my review page said which was which. I still preferred the old version of four of the seven works. I overruled the judges anyway. Three works stay as they were, and a film goes back to the drawing board.
Was I right? I can't prove it. What I can show, without arguing about taste at all, is how much else the judges were reading besides the pictures.
The Neighbour
Every judge in the test also got one trick pair: the same pictures on both sides, with only the labels A and B to tell them apart. A judge that finds a difference there is inventing one. All four passed. Identical scores on both sides, and the lowest confidence the scale allowed in whichever side they picked.
That trick pair is where Gemini gave the old pictures their 8. Then it saw the same files beside the new version and gave them a 6. The other three judges moved those pictures by half a point at most. Gemini moved them by two full points, and its notes now described a worse picture.
I ran each pair once, so some of that could be noise. One study found that an older Gemini Flash shifts its score by about one and a half points on average when the very same request is simply repeated. On my pair, though, the other three held steady.
Television engineers have a name for this: a contextual effect. Their international standard for rating picture quality, BT.500, reports laboratory tests in which the grade viewers gave a picture shifted with whatever they had seen just before it. Only one of the methods tested showed no such shift. It pairs every picture with the untouched original, never says which is which, shuffles the slots at random, and asks for a grade for both.
Gemini's scores also decided which works counted as clearly improved. For that I had set a stricter bar than a vote: at least two of the three judges had to score the new version a full point higher. In every one of the seven works, Gemini's gap between old and new was the widest of the three, once by more than three points in favour of the old version. With Gemini on the panel, four works passed. Put GPT in its seat and only two do. Swap one judge, and half of my "clear improvements" disappear.
First Place Wins
My films have soundtracks, and Gemini is the only judge I run that listens to audio files. I asked it to compare three versions of the music under two films, each set twice, in two different orders. In all four runs, the file that played first won.
One soundtrack, sent byte for byte the same, got a 9 in the first slot and a 4 in the second, where Gemini suddenly heard six seconds of "dead air". Another went from 3.5 to 8.5 when it moved to the front. Same recording.
Tap to enlarge.
The one controlled study of music judges I found, from early October, tested open models that anyone can download rather than mine. But it tried the tricks I had stumbled into, and a bolder one: it took the sound away. With the sound on, the judges' verdicts lined up with the experts' only weakly. With the sound removed, they did no better than a guess based on nothing but the written description the music was generated from. One model picked the second clip in 99 percent of pairs.
What the Judge Never Saw
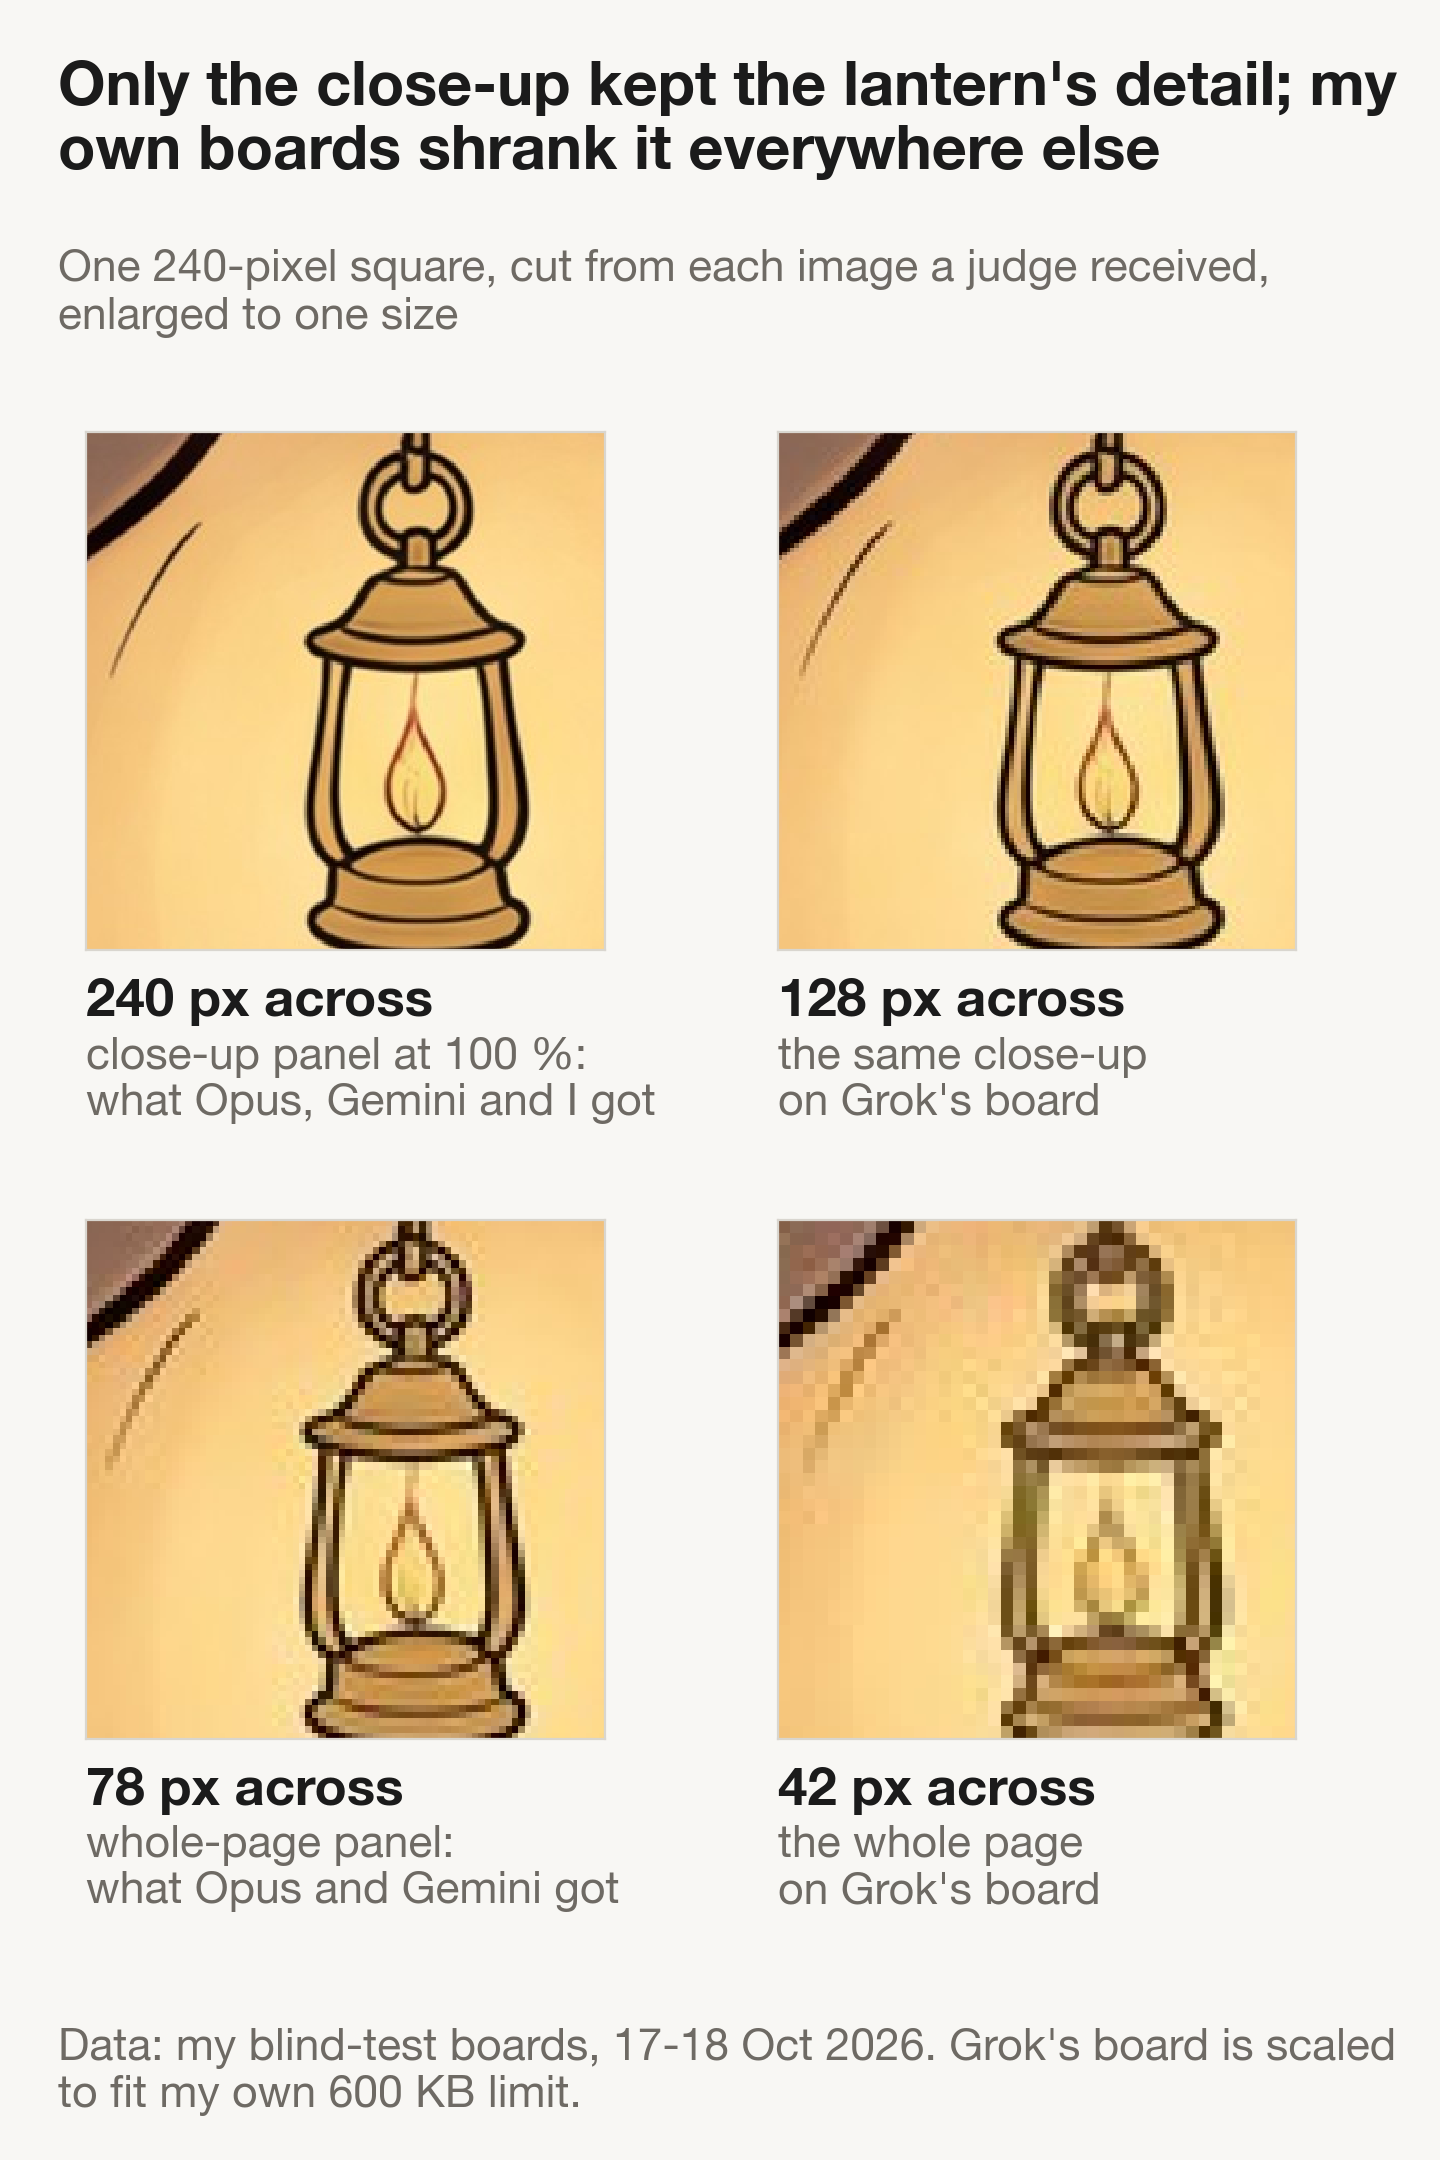
Grok gets my images through an add-on I wrote, and that add-on caps how much image data goes out per run. The cap is mine, not xAI's. When Grok reviewed screenshots of my website redesign, it saw them at roughly a third of their width. It read "606 px" in a code sample as 666 and got a button colour wrong. To be fair, nine of its ten findings still held up.
Gemini, by default, spends at most a fixed number of tokens, the units a model reads, on any one image, so a picture with twice as many pixels got no more of them. My own review boards, the sheets of pictures I put in front of each judge, did the rest: they shrank every full page before any judge saw it, and only the close-ups kept the finest detail.
Tap to enlarge.
Measuring this cost me an explanation I liked. I had assumed the old versions looked better to me because a paid model had drawn them at a higher resolution. Then I checked. In the picture book, old and new scenes are about the same size: most old scenes had already been redrawn by the same free tool. My favourite theory explains one of my four "old is better" verdicts cleanly. Not the other three.
The Judge Nobody Tested
My social-media bot has an image judge that I tuned in September against Claude Sonnet 5, on about sixty earlier images. Its settings name the model only as "sonnet", a nickname the provider can point at a newer model. Less than a week later, it did. Since the tuning, more than four out of five of its checks have run on a model I never tested for this job.
In September I also wrote that my reviewer would look at the first ten images the bot published under that judge, and that more than two with a visible defect would make the judge's rule stricter. The tenth went out in October. Two AI reviewers looked at all ten without seeing the judge's scores. Between them they called two images clearly defective, plus a few borderline cases. Counting the clear ones, the rule holds. Counting the borderline ones too, it falls.
My favourite is a capital letter V. The bot had asked for a vee block, a machinist's steel block with a V-shaped groove for holding round parts. The judge's own notes said the image "reads strongly as the letter 'V' glyph". It passed.
Breaking a Picture on Purpose
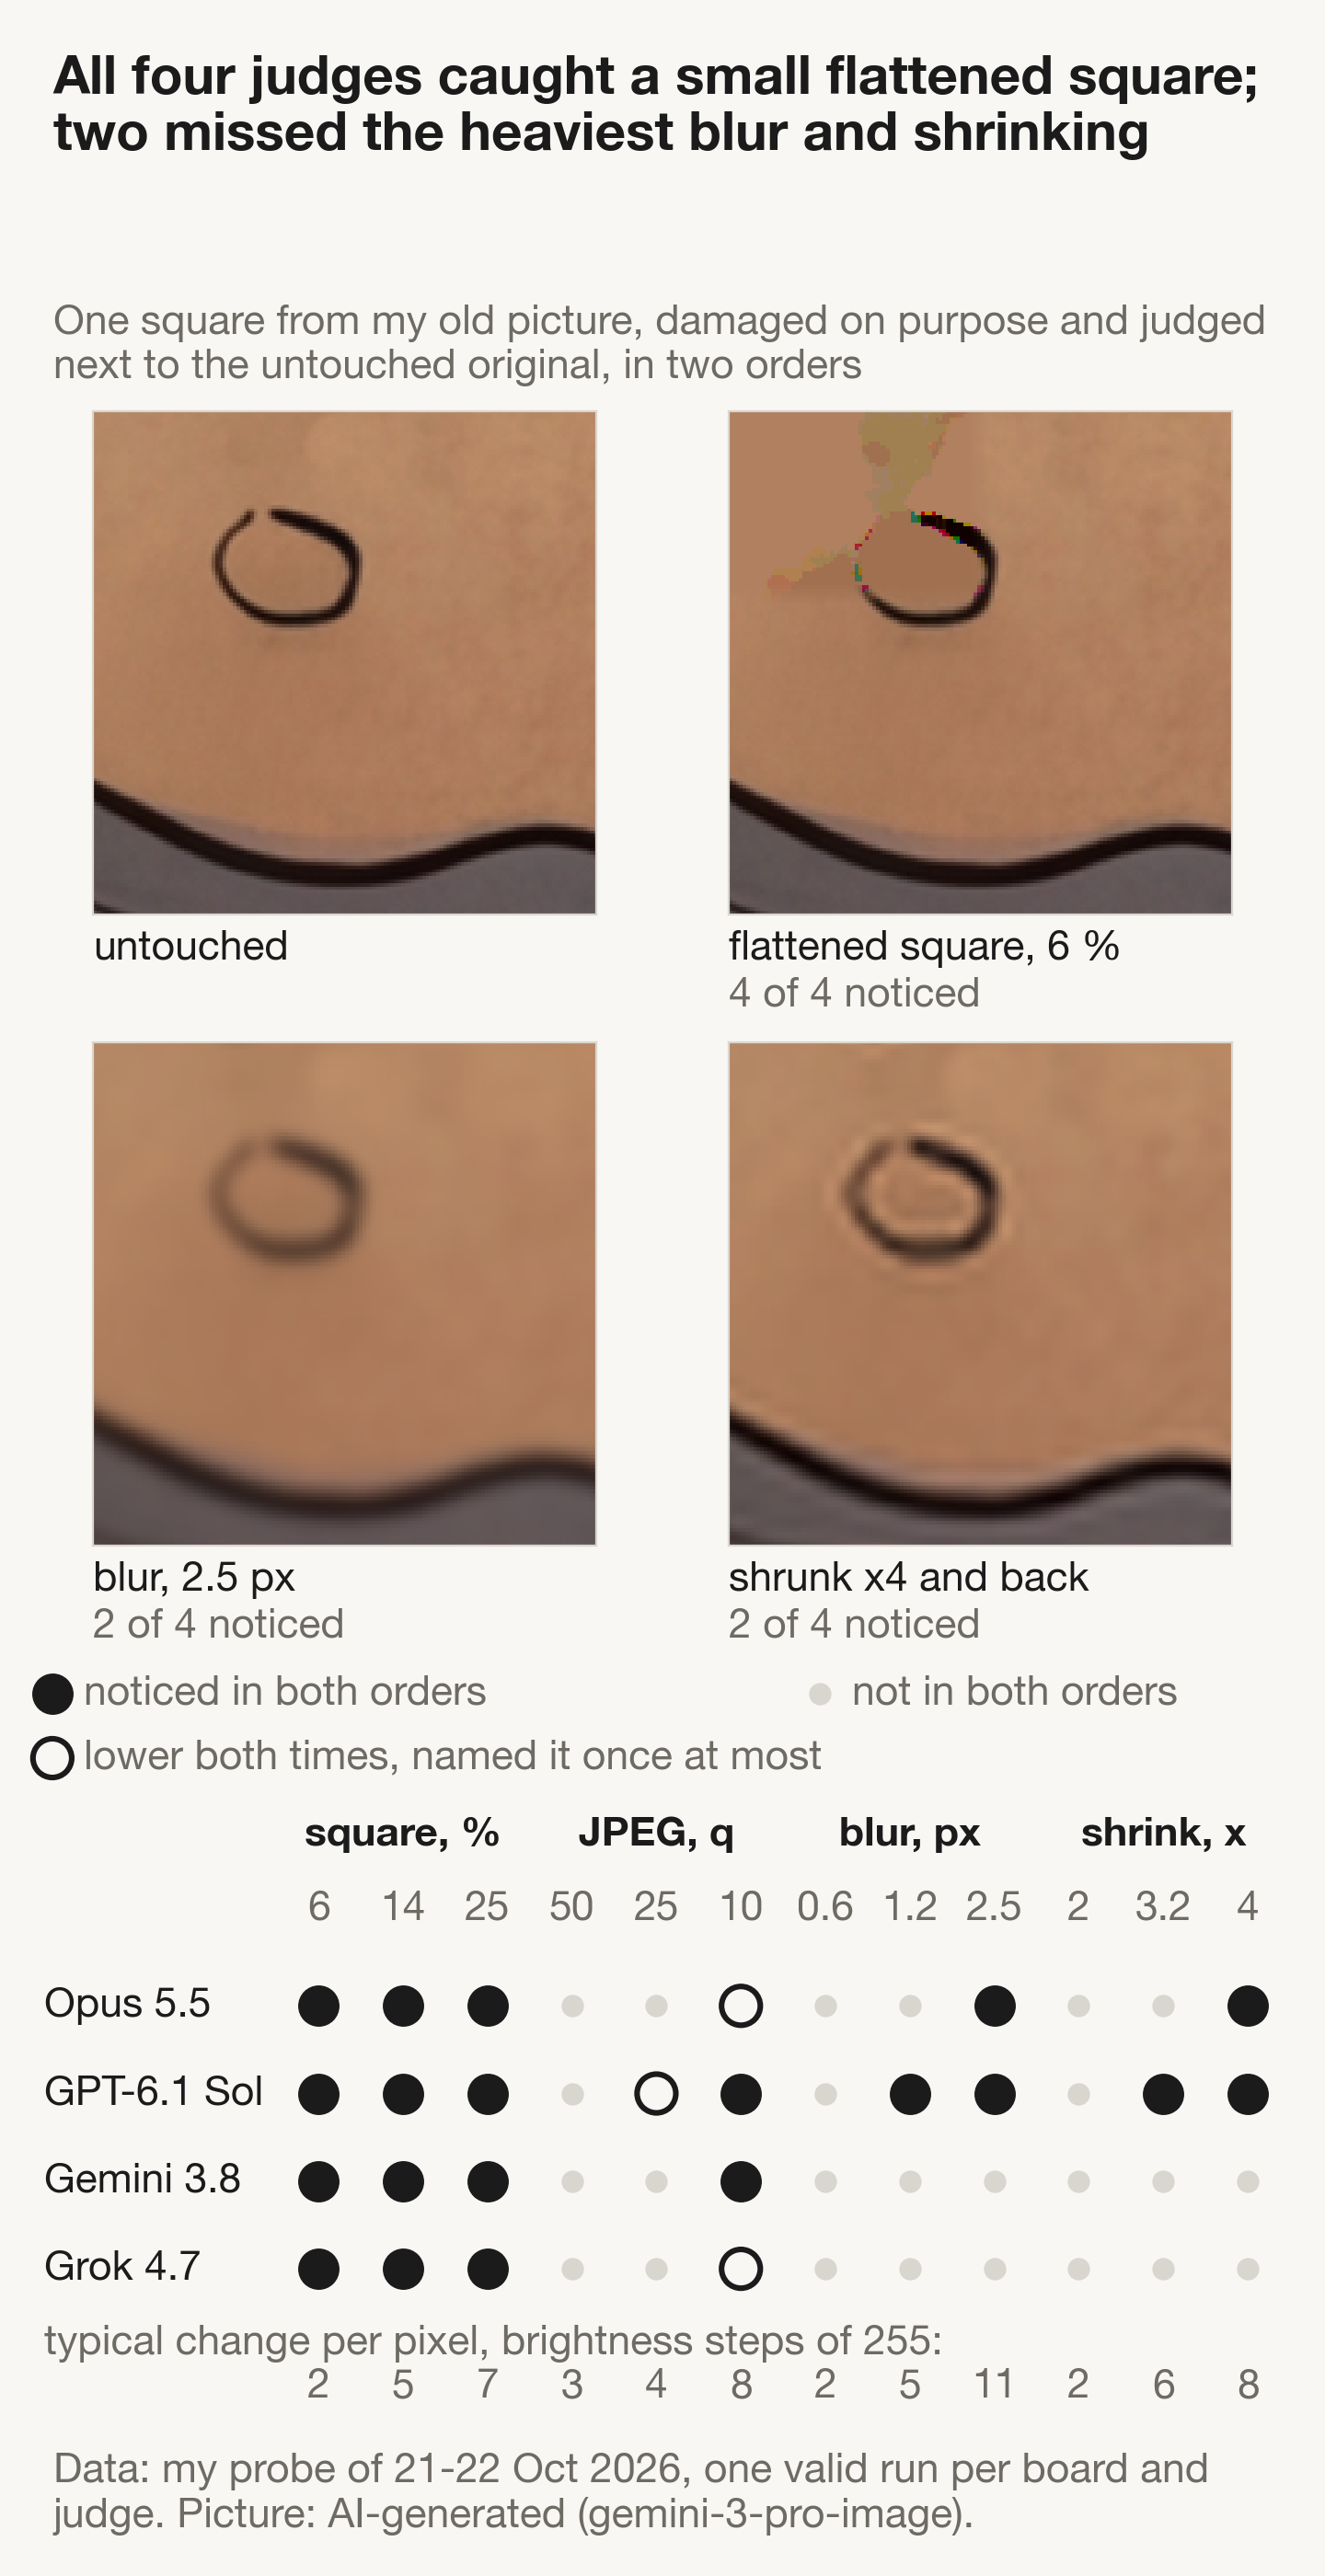
Taste is hard to measure. Damage isn't. So I took one close-up from the old hidden-object picture and broke it on purpose, in four ways and at three strengths each: shrinking it and blowing it back up, blurring it, compressing it hard as a JPEG, and flattening one small square with a filter, fewer tones and smoothed strokes, the kind of patch Opus had once described as "inserted rather than painted".
Most boards showed the untouched original next to three damaged tiles in shuffled positions, and every kind of damage appeared on two boards, so each judge saw it in two orders. Claude Opus, GPT, Gemini and Grok judged them all. I wrote down the rules and my predictions, time-stamped, before the first run.
Which damage did all four judges notice: the tile shrunk to a sixteenth of its pixels and blown back up, the tile blurred from edge to edge, or the small flattened square covering six percent of it?
All four found the square, in both orders, and pointed right at it. Opus called it "posterization", GPT a "rectangular patch". Gemini blamed it on compression every time: right place, wrong cause. I had predicted the opposite: hardly any of the judges from the blind test would catch the little square, and all of them would catch the heavy blur and the heavy shrink.
Measured over the whole tile, the square was one of the smallest changes on any board. The blur changed the tile about five times as much, and Grok gave it a perfect 10, both times, exactly what it gave the original. Gemini caught the blur in one order. In the other, it handed the untouched original the same score and the same sentence, word for word: "The entire tile suffers from noticeable blur". The heavily shrunk tile got perfect 10s from both Grok and Gemini. Opus and GPT caught the heavy blur and the heavy shrink, in both orders. A milder shrink, about what the free image tool's resolution does to a full printed page, only GPT caught in both orders. The crude, blocky JPEG, everybody marked down.
Tap to enlarge.
Spot the damage
Pick a kind of damage, tap the tile you think is untouched, and see what each of the four judges scored every tile on that board and what it wrote.
The neighbour struck again, this time in Opus. The untouched tile, the same pixels on every board, got anything from 7 to a perfect 10 from Opus from one board to the next. Beside three blank grey tiles, Opus found four flaws in it. Beside the flattened squares, none. I had predicted the neighbour would move Gemini and leave Opus alone. Wrong again.
So in my probe, a patch that disagreed with its surroundings was caught by every judge, while a loss spread evenly over the whole tile fooled two of the four. That matters, because a low-resolution picture printed across a full page is an even loss of exactly that kind. It was one picture and one run per board, so I read it as a hint.
Other People's Numbers
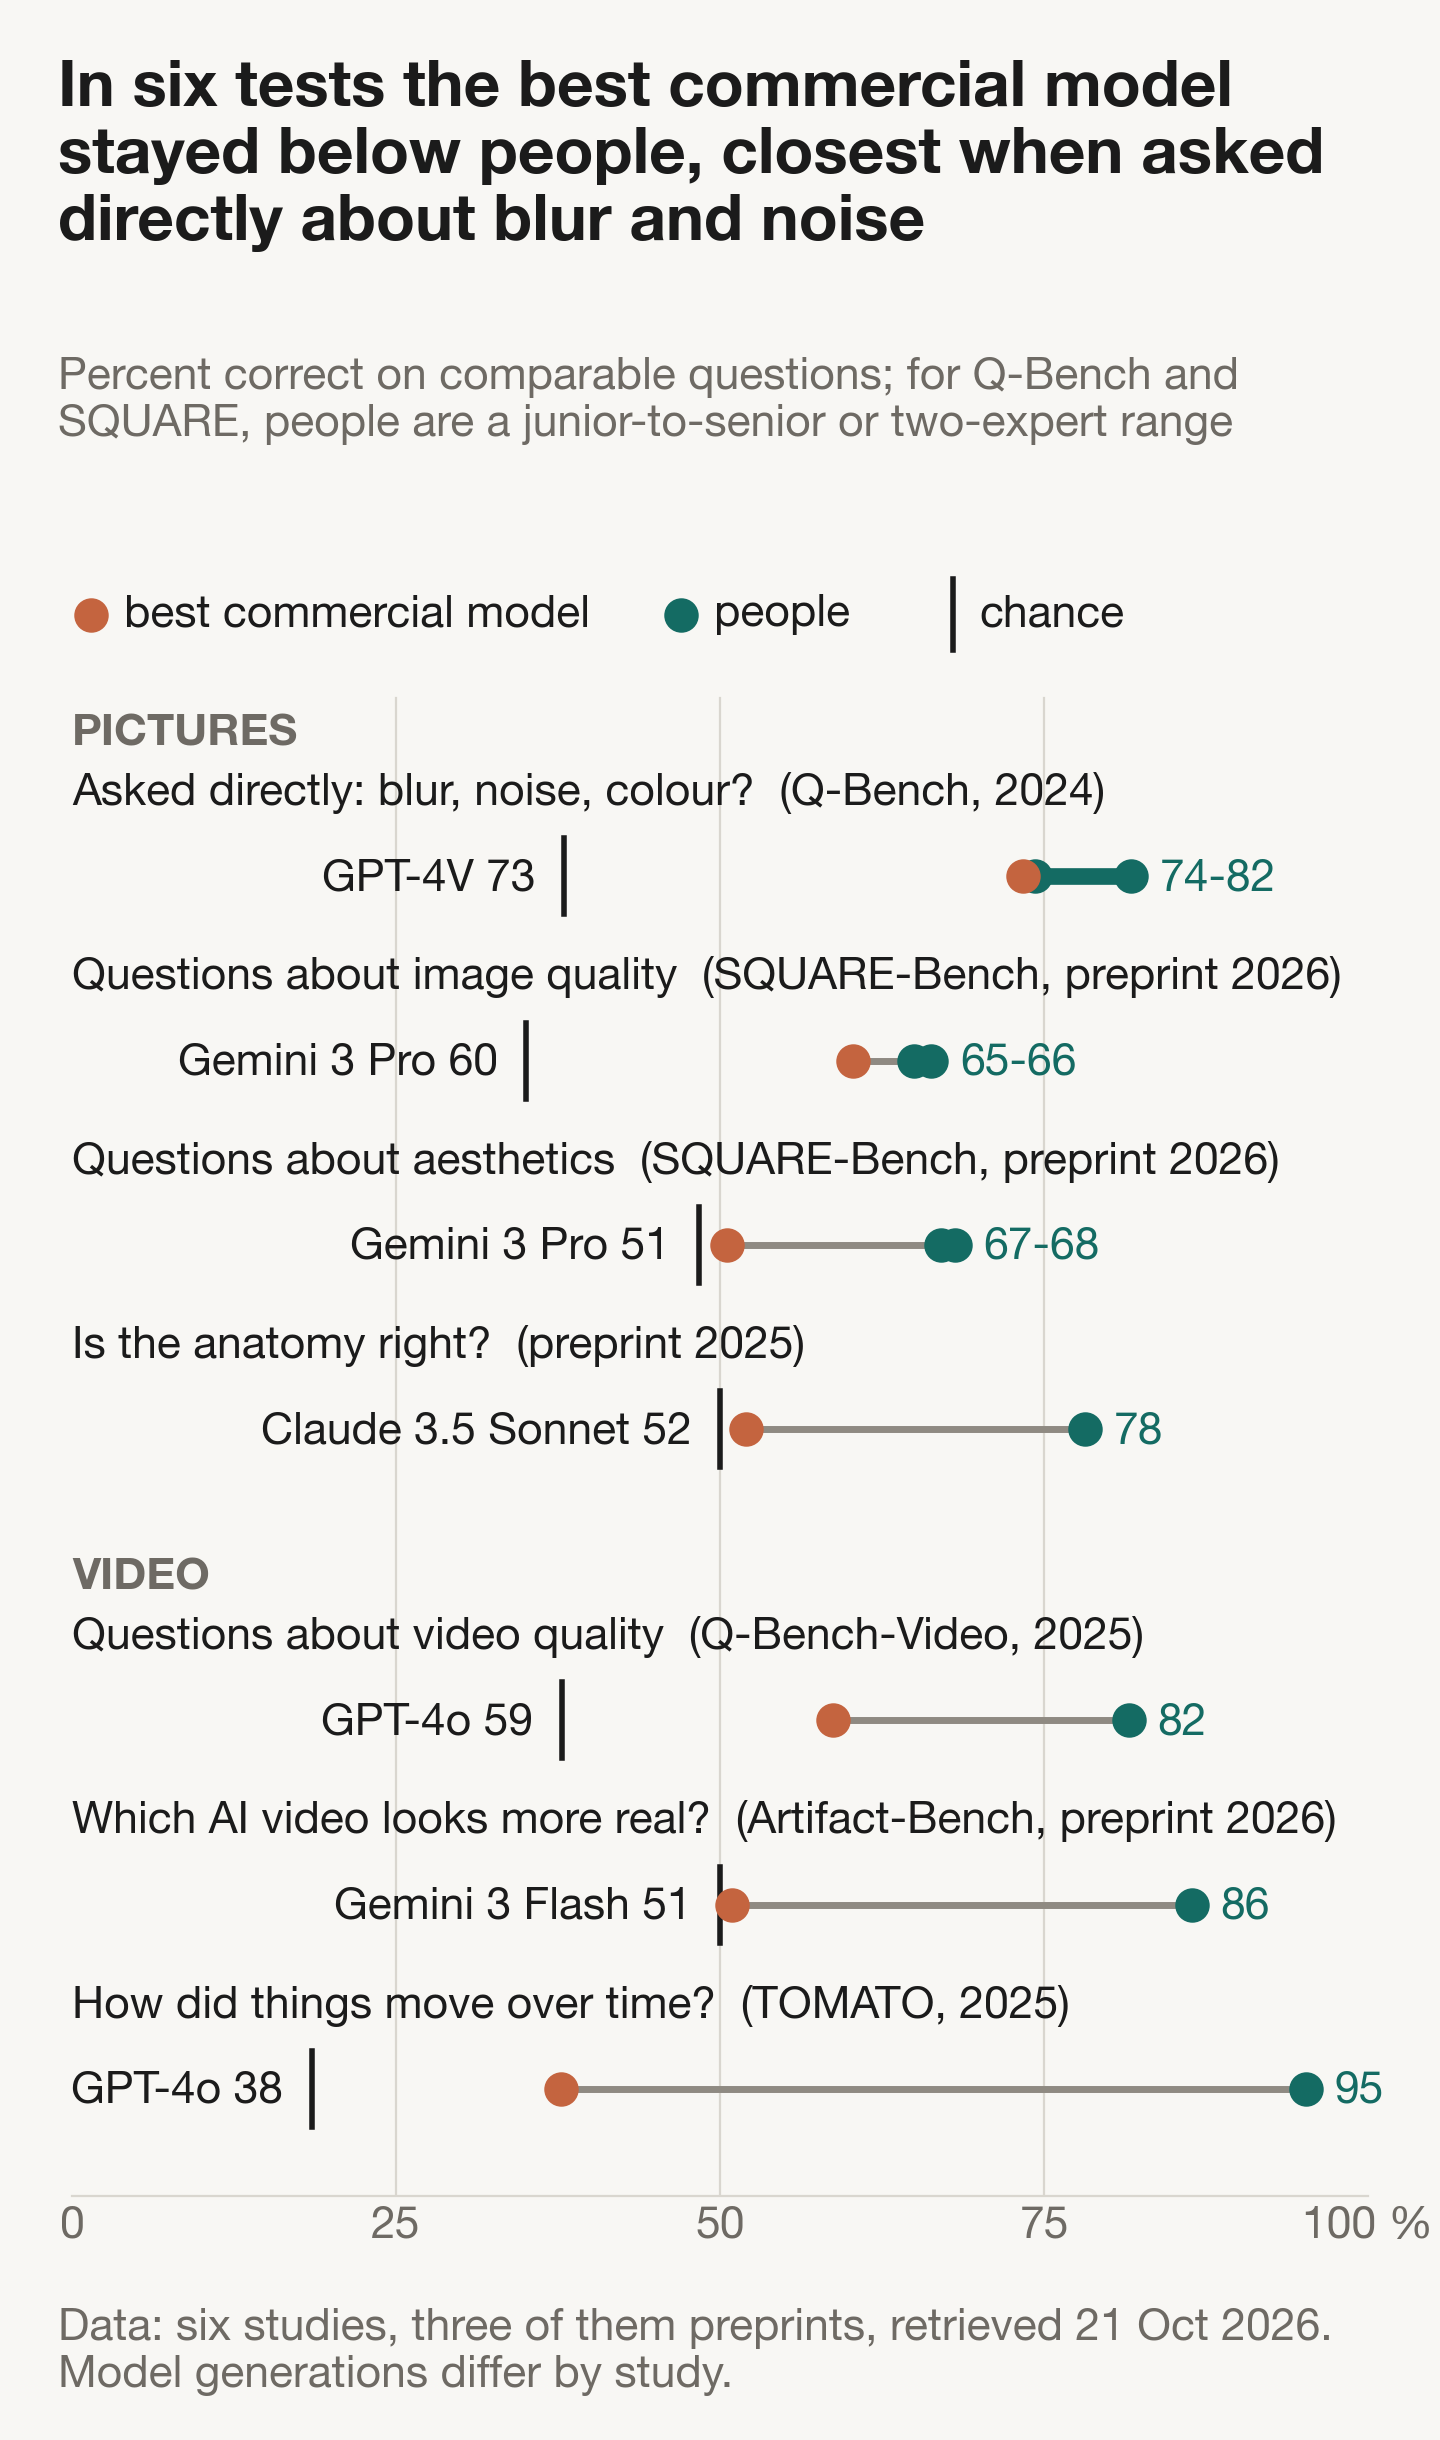
In one September benchmark, Gemini 3 Pro ranked first among the judges at saying what a picture shows (the objects, the scene, the text in it) and seventeenth at saying how good it looks. On another, it matched expert preferences on hard pairs of generated images nearly three times in four, better than any model built only to score images. So the judges aren't hopeless. In that first benchmark, they were better at "what" than at "how good".
Where a picture breaks the rules, they can fall apart. In a study presented at ICLR this year, called VLMs are Biased, five leading models looked at 273 pictures of animals drawn with one extra leg, twice each, and counted the legs correctly in about two percent of their answers. Asked which of two AI videos looked more real, Google's models were right about half the time, a coin flip; experts were right more than eight times in ten. And a popular video benchmark advertises up to 99 percent agreement with humans. Each of those percentages measures how closely a judge puts four video generators in the same order people do: four data points.
Tap to enlarge.
Who Keeps the Taste
So how good are today's AI models at judging pictures and video? Good at a question I can write down before the test and check after it: is there a patch, what does the logo say, is half the frame empty. In a reading test I had fixed in advance, Gemini and Grok read my company's logo, set in a tiny pixel font, correctly on every screenshot. Gemini watched the launch film of one of my product websites and caught a list entry that never appeared on screen, and a right half of the frame that sat empty for more than three seconds. Both were real, and both got fixed.
Unreliable at "which one is better". Not for lack of an opinion: they have one for every pair, with a confidence attached. But the opinion belongs to the setup as much as to the picture: the neighbour, the slot, the pixels my own tools let through, and whichever model currently answers to the name.
I would not let any of the four decide which of my pictures goes to print. I would let each of them check one thing I can name in advance, the way the TV engineers' steadiest method does it: paired with the untouched original, without saying which is which. To that I would add two rules of my own: both orders, and full size. That layout did not stop the neighbour in my probe; Opus still graded the untouched tile anywhere from 7 to 10. What held was the finding: the square was caught in both orders. So I would use a judge to find a defect I named in advance, never for its grade. And my agents now have to show me a few before-and-after samples before they rebuild a whole visual work.
I still don't know whether I was right about those four works. Finding out needs people who have seen neither version, and boards without labels. That is a test with humans, and I have not run it.
Where the Numbers Come From
The blind test ran on 17 and 18 October 2026 on seven finished works plus two earlier rebuilds. The counted judges were a fresh Claude Opus session, Grok 4.7 and Gemini 3.8 Flash, pinned to that version from 18 October; GPT-6.1 Sol, run through OpenAI's Codex tool, was an uncounted fourth voice. For most works, each version was shown as three panels (a first impression, the whole page, one panel with two close-ups at full size); every version came with a description, the scoring rules and a list of what a buyer receives, and scores were weighted over six aspects. For every work, two of the four judges saw the new version as A and two as B. The opening scores are Gemini's sub-score for visual execution at 09:31 and 09:33 Berlin time on 18 October. In the blind test Gemini and Opus wrote their notes in German; the quotes from them are my translations. My own verdicts came on 18 October from a page that showed labels and the judges' results. The soundtrack runs are from 12 October; identical files are identified by their SHA-256 hash, and the model behind each answer comes from my audit log.
The damage probe used one 768-pixel crop, four kinds of damage at three strengths and ten boards, judged by Claude Opus 5.5, GPT-6.1 Sol, Gemini 3.8 Flash and Grok 4.7. Rules, predictions and the hash of the answer key were committed before the first run. Three Gemini boards failed on 21 October, two of them twice on a server overload and one on the daily quota. A dated addendum, committed before any further run, gave the two overload boards one third attempt; the quota board got its regular second one. All three were answered on 22 October, so every judge has one valid answer per board. "About five times as much" compares the root-mean-square difference from the original in 8-bit brightness steps: about 2 for the square, 11 for the blur, 8 for the heavy shrink. The bot's judge was tuned on 23 September on 62 images; the alias moved to Sonnet 5.5 on 29 September, and 112 of its 137 checks up to 21 October ran on that model. The ten bot images were labelled by Claude Opus agents with my written style rules, so they are cousins of the judge they check. Research figures come from SQUARE-Bench, Multimodal RewardBench 2 (CVPR 2026), VLMs are Biased (ICLR 2026), VBench-2.0, Artifact-Bench, a preprint on music judges (9 October 2026) and one on repeated scoring (1 October 2026); the fourth figure adds Q-Bench, Q-Bench-Video, TOMATO and a 2025 preprint on image anatomy. All were retrieved on 21 and 22 October 2026. Several are preprints, and none tests the exact model versions I use.
Checks that pass for the wrong reason are what my book Nobody Opens a Passing Check is about.
